class: center, middle, inverse, title-slide .title[ # PADP 7120 Data Applications in PA ] .subtitle[ ## Data Description ] .author[ ### Alex Combs ] .institute[ ### UGA | SPIA | PADP ] .date[ ### Last updated: September 14, 2026 ] --- # Outline - Distinguish between descriptive and inferential statistics - Identify population, sample, parameter, and statistic - Distributions and their description --- # Two categories of statistics .center[ 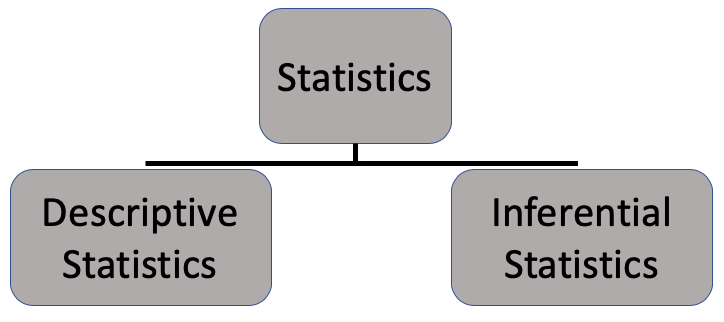 ] --- # Population vs. Sample - **Population:** all members of a specified group pertaining to a research question - A population can be any size based on our research question - If we can observe the population, all we need to do is describe it to reach useful conclusions -- - **Sample:** a subset of our target population - We can describe a sample or a population - If we cannot observe the population, we take a sample and use inferential statistics to reach useful conclusions about that population --- # Descriptive vs. inferential - Suppose we survey a subset of MPA graduates to learn about employment and earning outcomes. - Are the following questions **descriptive** or **inferential**? -- - What is the average income of respondents? -- - What is the average income of MPA graduates? -- - What percent of respondents are employed? -- - Does an MPA increase income? --- # Parameter vs. statistic - **Parameter:** a measure pertaining to a population - The "true" value we try to estimate if the population is unobserved - **Statistic:** a measure pertaining to a sample - Also referred to as an **estimate** --- # Survey Example Suppose our survey of UGA MPA alumni receives 100 responses and and the median income of respondents is $80,000. - Is this a sample statistic or a population parameter? --- # Descriptive vs. inferential Suppose we want to know the average salary of college-educated women in Georgia. We survey a sample of 1,000 college-educated women in Georgia and record their income. -- - What is the population and what is the sample? -- - What is the parameter we intend to estimate? -- - What is the statistic we will use to estimate the parameter? --- class: inverse, middle, center # Data description --- # Distribution - A distribution shows the (possible) values for a variable and how often they occur. <img src="Description_files/figure-html/unnamed-chunk-2-1.png" alt="" style="display: block; margin: auto;" /> --- # Describing numerical variables - Center - Mean, median, mode - Spread - Variance, standard deviation, IQR, range - Association - Covariance, correlation - Regression coefficient, coefficient of determination (will cover later) --- # Measures of center - Mean: the balancing point of the distribution - Median: the middle of the distribution (50th percentile) - Mode: the peak(s) of the distribution --- # Mean (average) `$$\bar{x}={\frac {1}{n}}\sum _{i=1}^{n}x_{i}={\frac {x_{1}+x_{2}+\cdots +x_{n}}{n}}$$` - Sum of all values and divide by the number of values .pull-left[ <table> <thead> <tr> <th style="text-align:right;"> ID </th> <th style="text-align:right;"> variable </th> </tr> </thead> <tbody> <tr> <td style="text-align:right;"> 1 </td> <td style="text-align:right;"> 2 </td> </tr> <tr> <td style="text-align:right;"> 2 </td> <td style="text-align:right;"> 4 </td> </tr> <tr> <td style="text-align:right;"> 3 </td> <td style="text-align:right;"> 6 </td> </tr> <tr> <td style="text-align:right;"> 4 </td> <td style="text-align:right;"> 8 </td> </tr> <tr> <td style="text-align:right;"> 5 </td> <td style="text-align:right;"> 10 </td> </tr> </tbody> </table> ] .pull-right[ ``` r (2 + 4 + 6 + 8 + 10)/5 ``` ``` ## [1] 6 ``` <img src="lectures_files/mean.png" alt="" width="1105" /> ] --- # Mean - In R, can use the `mean(data$variable)` function ``` r mean(data$variable) ``` ``` ## [1] 6 ``` ``` r mean(ncbirths$weeks) ``` ``` ## [1] 38.4675 ``` --- # Median - Arrange values in order, find the middle value - If no middle value because even number of values, average the two middle values .pull-left[ <table> <thead> <tr> <th style="text-align:right;"> ID </th> <th style="text-align:right;"> variable </th> </tr> </thead> <tbody> <tr> <td style="text-align:right;"> 1 </td> <td style="text-align:right;"> 2 </td> </tr> <tr> <td style="text-align:right;"> 2 </td> <td style="text-align:right;"> 4 </td> </tr> <tr> <td style="text-align:right;"> 3 </td> <td style="text-align:right;"> 6 </td> </tr> <tr> <td style="text-align:right;"> 4 </td> <td style="text-align:right;"> 8 </td> </tr> <tr> <td style="text-align:right;"> 5 </td> <td style="text-align:right;"> 10 </td> </tr> </tbody> </table> ] .pull-right[ ``` r median(data$variable) ``` ``` ## [1] 6 ``` 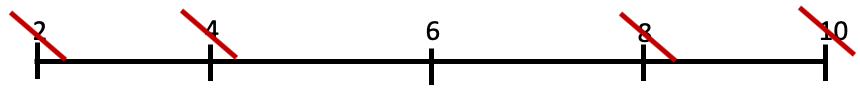 ``` r median(ncbirths$weeks) ``` ``` ## [1] 39 ``` ] --- # Mode - The value that occurs most frequently .pull-left[ <table> <thead> <tr> <th style="text-align:right;"> ID </th> <th style="text-align:right;"> variable </th> </tr> </thead> <tbody> <tr> <td style="text-align:right;"> 1 </td> <td style="text-align:right;"> 2 </td> </tr> <tr> <td style="text-align:right;"> 2 </td> <td style="text-align:right;"> 4 </td> </tr> <tr> <td style="text-align:right;"> 3 </td> <td style="text-align:right;"> 6 </td> </tr> <tr> <td style="text-align:right;"> 4 </td> <td style="text-align:right;"> 8 </td> </tr> <tr> <td style="text-align:right;"> 5 </td> <td style="text-align:right;"> 10 </td> </tr> </tbody> </table> ] .pull-right[ - Variable has no mode. One more of any of the 5 values would make that value the mode. ] --- # Mean vs. median vs. mode - We use measures of center to communicate the *typical* value of a distribution. - Which measure best conveys what is typical depends on the distribution. 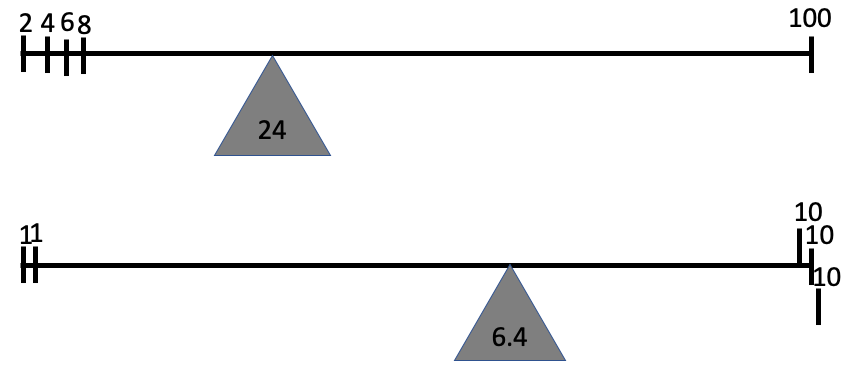 --- # Mean vs. median vs. mode - Mean is sensitive to extreme values, median is not - Median may be better to use when a distribution is skewed - Mode is useful for discrete or categorical variables with few possible values --- # Mean vs. median vs. mode - If distribution is symmetrical, little difference between mean and median .pull-left[ <img src="Description_files/figure-html/unnamed-chunk-13-1.png" alt="" style="display: block; margin: auto;" /> ] .pull-right[ ``` r mean(ncbirths$weeks) ``` ``` ## [1] 38.4675 ``` ``` r median(ncbirths$weeks) ``` ``` ## [1] 39 ``` ] --- # Mean vs. median vs. mode - As distribution becomes skewed, mean and median begin to differ .pull-left[ <img src="Description_files/figure-html/unnamed-chunk-15-1.png" alt="" style="display: block; margin: auto;" /> ] .pull-right[ ``` r mean(gapminder$gdpPercap) ``` ``` ## [1] 7215.327 ``` ``` r median(gapminder$gdpPercap) ``` ``` ## [1] 3531.847 ``` ] --- class: inverse, middle, center # Measures of spread --- # Measures of spread - **Variance:** the average squared deviation from the mean - **Standard deviation:** the average deviation from the mean - **Interquartile range:** the difference between 75th and 25th percentiles - **Range:** the difference between the maximum and minimum values --- # Variance `$$S^2={\frac {1}{n-1}}\sum _{i=1}^{n}(x_{i}-\bar{x})^2={\frac {(x_{1}-\bar{x})^2+(x_{2}-\bar{x})^2+\cdots +(x_{n}-\bar{x})^2}{n-1}}$$` <table> <thead> <tr> <th style="text-align:right;"> ID </th> <th style="text-align:right;"> variable </th> <th style="text-align:right;"> xbar </th> <th style="text-align:right;"> deviation </th> <th style="text-align:right;"> devsquared </th> </tr> </thead> <tbody> <tr> <td style="text-align:right;"> 1 </td> <td style="text-align:right;"> 2 </td> <td style="text-align:right;"> 6 </td> <td style="text-align:right;"> -4 </td> <td style="text-align:right;"> 16 </td> </tr> <tr> <td style="text-align:right;"> 2 </td> <td style="text-align:right;"> 4 </td> <td style="text-align:right;"> 6 </td> <td style="text-align:right;"> -2 </td> <td style="text-align:right;"> 4 </td> </tr> <tr> <td style="text-align:right;"> 3 </td> <td style="text-align:right;"> 6 </td> <td style="text-align:right;"> 6 </td> <td style="text-align:right;"> 0 </td> <td style="text-align:right;"> 0 </td> </tr> <tr> <td style="text-align:right;"> 4 </td> <td style="text-align:right;"> 8 </td> <td style="text-align:right;"> 6 </td> <td style="text-align:right;"> 2 </td> <td style="text-align:right;"> 4 </td> </tr> <tr> <td style="text-align:right;"> 5 </td> <td style="text-align:right;"> 10 </td> <td style="text-align:right;"> 6 </td> <td style="text-align:right;"> 4 </td> <td style="text-align:right;"> 16 </td> </tr> </tbody> </table> ``` r (16+4+0+4+16)/4 ``` ``` ## [1] 10 ``` --- # Standard deviation (SD) - Variance does not make sense as a *descriptive* measure of spread ``` r var(ncbirths$weeks) ``` ``` ## [1] 7.583423 ``` - On average, weeks pregnant deviates from the average by 7.6 weeks squared. -- - Standard deviation recovers the original variable ``` r sd(ncbirths$weeks) ``` ``` ## [1] 2.753802 ``` - On average, weeks pregnant deviates from the average by almost 3 weeks. --- # Interquartile range (IQR) - Divide the distribution into 4 equal parts - Each dividing value is the 25th, 50th, and 75th percentiles - IQR is the difference between 25th and 75th percentiles ``` r quantile(ncbirths$weeks, c(.25, .5, .75)) ``` ``` ## 25% 50% 75% ## 38 39 40 ``` - The IQR for weeks pregnant is 2 -- ``` r IQR(ncbirths$weeks) ``` ``` ## [1] 2 ``` --- # SD vs. IQR - We use SD and IQR to communicate the typical deviation of a distribution from its center - SD is based on the mean; sensitive to extreme values - IQR uses percentiles; not sensitive to extreme values -- .pull-left[ <table> <thead> <tr> <th style="text-align:right;"> ID </th> <th style="text-align:right;"> variable </th> </tr> </thead> <tbody> <tr> <td style="text-align:right;"> 1 </td> <td style="text-align:right;"> 2 </td> </tr> <tr> <td style="text-align:right;"> 2 </td> <td style="text-align:right;"> 4 </td> </tr> <tr> <td style="text-align:right;"> 3 </td> <td style="text-align:right;"> 6 </td> </tr> <tr> <td style="text-align:right;"> 4 </td> <td style="text-align:right;"> 8 </td> </tr> <tr> <td style="text-align:right;"> 5 </td> <td style="text-align:right;"> 100 </td> </tr> </tbody> </table> ] -- .pull-right[ ``` r sd(extreme$variable) ``` ``` ## [1] 42.54409 ``` ``` r IQR(extreme$variable) ``` ``` ## [1] 4 ``` ] --- # SD vs. IQR .pull-left[ 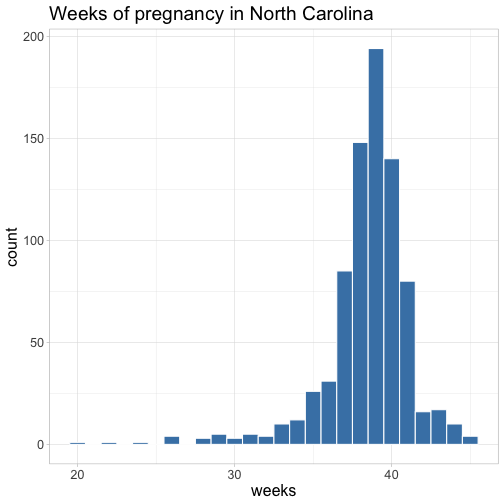<!-- --> ] .pull-right[ ``` r sd(ncbirths$weeks) ``` ``` ## [1] 2.753802 ``` ``` r IQR(ncbirths$weeks) ``` ``` ## [1] 2 ``` ] --- # SD vs. IQR .pull-left[ <img src="Description_files/figure-html/unnamed-chunk-28-1.png" alt="" style="display: block; margin: auto;" /> ] .pull-right[ ``` r sd(gapminder$gdpPercap) ``` ``` ## [1] 9857.455 ``` ``` r IQR(gapminder$gdpPercap) ``` ``` ## [1] 8123.402 ``` ] --- # Range .pull-left[ - Describes the greatest extent to which the variable changes - Or the possible values of the variable - Or how different are the most different observations ] -- .pull-right[ ``` r range(ncbirths$weeks) ``` ``` ## [1] 20 45 ``` ``` r range(gapminder$gdpPercap) ``` ``` ## [1] 241.1659 113523.1329 ``` ] --- # Keep the Distribution in Mind - Underlying distributions are often simplified into summary descriptive measures - Don't let these simplifications hide potential nuance in the underlying distribution --- # Keep the Distribution in Mind A city has a private high school and a public high school. Each year, students take a state standardized test. Student scores can range between 0-100. .pull-left[ - Private school - Mean: 80 ] .pull-right[ - Public school - Mean: 70 ] --- # Keep the Distribution in Mind A city has a private high school and a public high school. Each year, students take a state standardized test. Student scores can range between 0-100. .pull-left[ - Private school - Mean: 80 - Standard deviation: 5 ] .pull-right[ - Public school - Mean: 70 - Standard deviation: 12 ] --- # Keep the Distribution in Mind A city has a private high school and a public high school. Each year, students take a state standardized test. Student scores can range between 0-100. .pull-left[ - Private school - Mean: 80 - Standard deviation: 5 - Median: 80 ] .pull-right[ - Public school - Mean: 70 - Standard deviation: 12 - Median: 80 ] --- # Keep the Distribution in Mind A city has a private high school and a public high school. Each year, students take a state standardized test. Student scores can range between 0-100. .pull-left[ - Private school - Mean: 80 - Standard deviation: 5 - Median: 80 - Maximum: 100 ] .pull-right[ - Public school - Mean: 70 - Standard deviation: 12 - Median: 80 - Maximum: 100 ] --- # Keep the Distribution in Mind A city has a private high school and a public high school. Each year, students take a state standardized test. Student scores can range between 0-100. .pull-left[ - Private school - Mean: 80 - Standard deviation: 5 - Median: 80 - Maximum: 100 - Minimum: 65 ] .pull-right[ - Public school - Mean: 70 - Standard deviation: 12 - Median: 80 - Maximum: 100 - Minimum: 25 ] --- class: inverse, middle, center # Measures of Association --- # Conditional distributions - Distribution of a variable *given* another variable's values <img src="Description_files/figure-html/unnamed-chunk-31-1.png" alt="" style="display: block; margin: auto;" /> --- # Measures of association Suppose we want to investigate the association between the percent of a state population that is white and the percent of the state population that voted for Donald Trump. .pull-left[ <table> <thead> <tr> <th style="text-align:right;"> share_white </th> <th style="text-align:right;"> share_vote_trump </th> </tr> </thead> <tbody> <tr> <td style="text-align:right;"> 65 </td> <td style="text-align:right;"> 63 </td> </tr> <tr> <td style="text-align:right;"> 58 </td> <td style="text-align:right;"> 53 </td> </tr> <tr> <td style="text-align:right;"> 51 </td> <td style="text-align:right;"> 50 </td> </tr> <tr> <td style="text-align:right;"> 74 </td> <td style="text-align:right;"> 60 </td> </tr> <tr> <td style="text-align:right;"> 39 </td> <td style="text-align:right;"> 33 </td> </tr> <tr> <td style="text-align:right;"> 69 </td> <td style="text-align:right;"> 44 </td> </tr> </tbody> </table> ] .pull-right[ <img src="Description_files/figure-html/unnamed-chunk-34-1.png" alt="" style="display: block; margin: auto;" /> ] --- # Measures of association - Or percent of white population in poverty <img src="Description_files/figure-html/unnamed-chunk-35-1.png" alt="" style="display: block; margin: auto;" /> - Units with higher values along the x-axis tend to have higher or lower values along the Y axis. Or no tendency. --- # Measures of association - The association between two variables can be described in terms of - **Direction:** when one variable increases, does the other variable *tend* to increase or decrease - **Strength:** how closely do the variables move together along a linear path - **Magnitude:** when one variable increases a certain amount, how much does the other variable increase or decrease --- # Measures of association - **Covariance:** measures **direction** of association between two variables - **Correlation coefficient:** measures **direction** and **strength** of association between two variables - **Regression coefficient:** measures the **direction** and **magnitude** of association between an explanatory variable and an outcome variable --- # Covariance `$$COV(X,Y)={\frac {1}{n-1}}\sum _{i=1}^{n}(x_{i}-\bar{x})(y_{i}-\bar{y})$$` - A positive value means X and Y tend to move in the same direction - A negative value means X and Y tend to move in opposite directions ``` r cov(state_trump$share_white_poverty, state_trump$share_vote_trump) ``` ``` ## [1] 11.70204 ``` - Result does not tell us if the association is strong or weak - Need to rescale it according to the spread of X and Y --- # Pearson's correlation coefficient `$$r_{x,y} = \frac{COV(X,Y)}{S_{x} \cdot S_{y}}$$` - Ranges between -1 and 1 - Positive or negative value tells us the direction - The closer to -1 or 1, the stronger the association in that direction, with 0 indicating no association - No definitive scale; rule of thumb: - 0.8: very strong - 0.6: strong - 0.4: moderate - 0.2: weak --- # Correlation coefficient <img src="Description_files/figure-html/unnamed-chunk-37-1.png" alt="" style="display: block; margin: auto;" /> ``` r cor(state_trump$share_vote_trump, state_trump$share_white_poverty) ``` ``` ## [1] 0.4872326 ``` - What is the interpretation of this correlation coefficient? --- # Correlation Percent white population in poverty ``` r cor(state_trump$share_vote_trump, state_trump$share_white_poverty) ``` ``` ## [1] 0.4872326 ``` Percent population that is white ``` r cor(state_trump$share_vote_trump, state_trump$share_white) ``` ``` ## [1] 0.4220675 ``` Which correlation is stronger? --- # Correlation <img src="Description_files/figure-html/unnamed-chunk-41-1.png" alt="" style="display: block; margin: auto;" /> Unit of analysis is states. Is the correlation positive or negative? --- # Correlation <img src="Description_files/figure-html/unnamed-chunk-42-1.png" alt="" style="display: block; margin: auto;" /> ``` r cor(state_trump$median_house_inc, state_trump$share_vote_trump) ``` ``` ## [1] -0.5925995 ``` What is the interpretation? --- # Limitations of correlation - Measures only linear association - Sensitive to extreme values - Is necessary but not sufficient to claim causation --- class: inverse, middle, center # Describing categorical variables --- # Describing categorical variables .pull-left[ 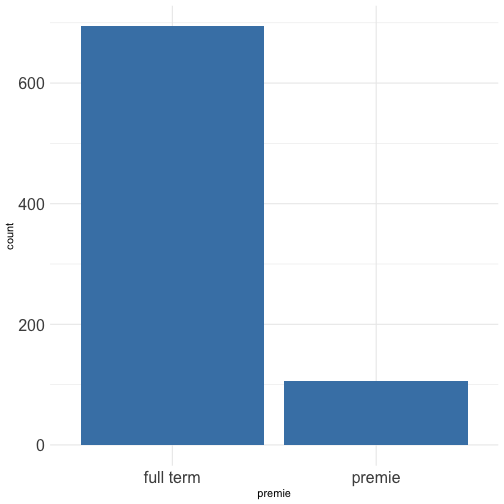<!-- --> ] .pull-right[ - There isn't a continuous distribution to calculate mean, median, variance, SD, IQR, or range. - Mode still works. - Frequency and cross-tabulations (contingency tables) are common. ] --- # Frequency Table - Can use the `table()` to get counts ``` r (premie.table <- table(ncbirths$premie)) |> kable(col.names = c('Term', 'Count')) ``` |Term | Count| |:---------|-----:| |full term | 694| |premie | 106| --- # Frequency table - Can use `prop.table()` on the saved result of `table()` to get proportions ``` r prop.table(premie.table) |> kable(digits = 2, col.names = c('Term', 'Proportion')) ``` |Term | Proportion| |:---------|----------:| |full term | 0.87| |premie | 0.13| --- # Contingency Table or Cross-tab ``` r (mytable <- table(ncbirths$habit, ncbirths$premie)) |> kable() ``` | | full term| premie| |:---------|---------:|------:| |nonsmoker | 625| 91| |smoker | 69| 15| - Tabulates the intersections between levels of two categorical variables - Common to use proportions or percentages - Important whether you use row or column percentages --- # Contingency Table ``` r prop.table(mytable, 1) |> kable(digits = 2) ``` | | full term| premie| |:---------|---------:|------:| |nonsmoker | 0.87| 0.13| |smoker | 0.82| 0.18| - This table reports row proportions; note each row sums to 1 - This table conveys the relative frequency of term levels conditional on smoking status level - "Among non-smoking mothers, 87% carried full-term and 13% had premature births." --- # Contingency Table ``` r prop.table(mytable, 2) |> kable(digits = 2) ``` | | full term| premie| |:---------|---------:|------:| |nonsmoker | 0.9| 0.86| |smoker | 0.1| 0.14| - This table reports column proportions; note each column sums to 1 - Conditional on term status, the relative frequency of smoking - "Among full-term births, 90% came from non-smoking mothers and 10% came from smoking mothers." --- # Contingency Table - If your question involves an outcome and a possible explanation - Place the outcome in the columns - Use row percentages --- # Recap - Difference between descriptive and inferential statistics; sample and population - When presented with descriptive statistics, consider what they say and don't say about the underlying distribution. - Correlation is a building block of how we explain or predict phenomena in our world using statistics.